
The App Store opened in 2008 with 500 apps. Companies that got in early owned distribution that later competitors had to buy. The same window is open right now — inside the AI apps your customers already use.
In November 2024, Anthropic published a spec called the Model Context Protocol — MCP. It is one standard that lets an AI app use real tools: your APIs, your data, your product's actions. Build one MCP server and Claude, ChatGPT, Cursor, VS Code and the rest can all use it. In December 2025 it stopped being one vendor's bet: Anthropic donated the protocol to the Linux Foundation's Agentic AI Foundation, co-founded with Block and OpenAI, with Google, Microsoft and AWS among its supporters.
The old way looks like this. Your customer is in Claude and needs something only your product knows. New tab, log in, find the screen, copy the number, paste it back into the chat. Call it the tab tax. MCP removes it: the assistant asks your server directly and the answer returns in the conversation.
This post walks the whole path — what the protocol actually is under the hood, how the spec reached its July 2026 revision, what the adoption numbers say once you check them, the business case for shipping a server, the questions a security review will ask, and what a production deployment looks like. Every claim has a source, and they are all linked at the end.
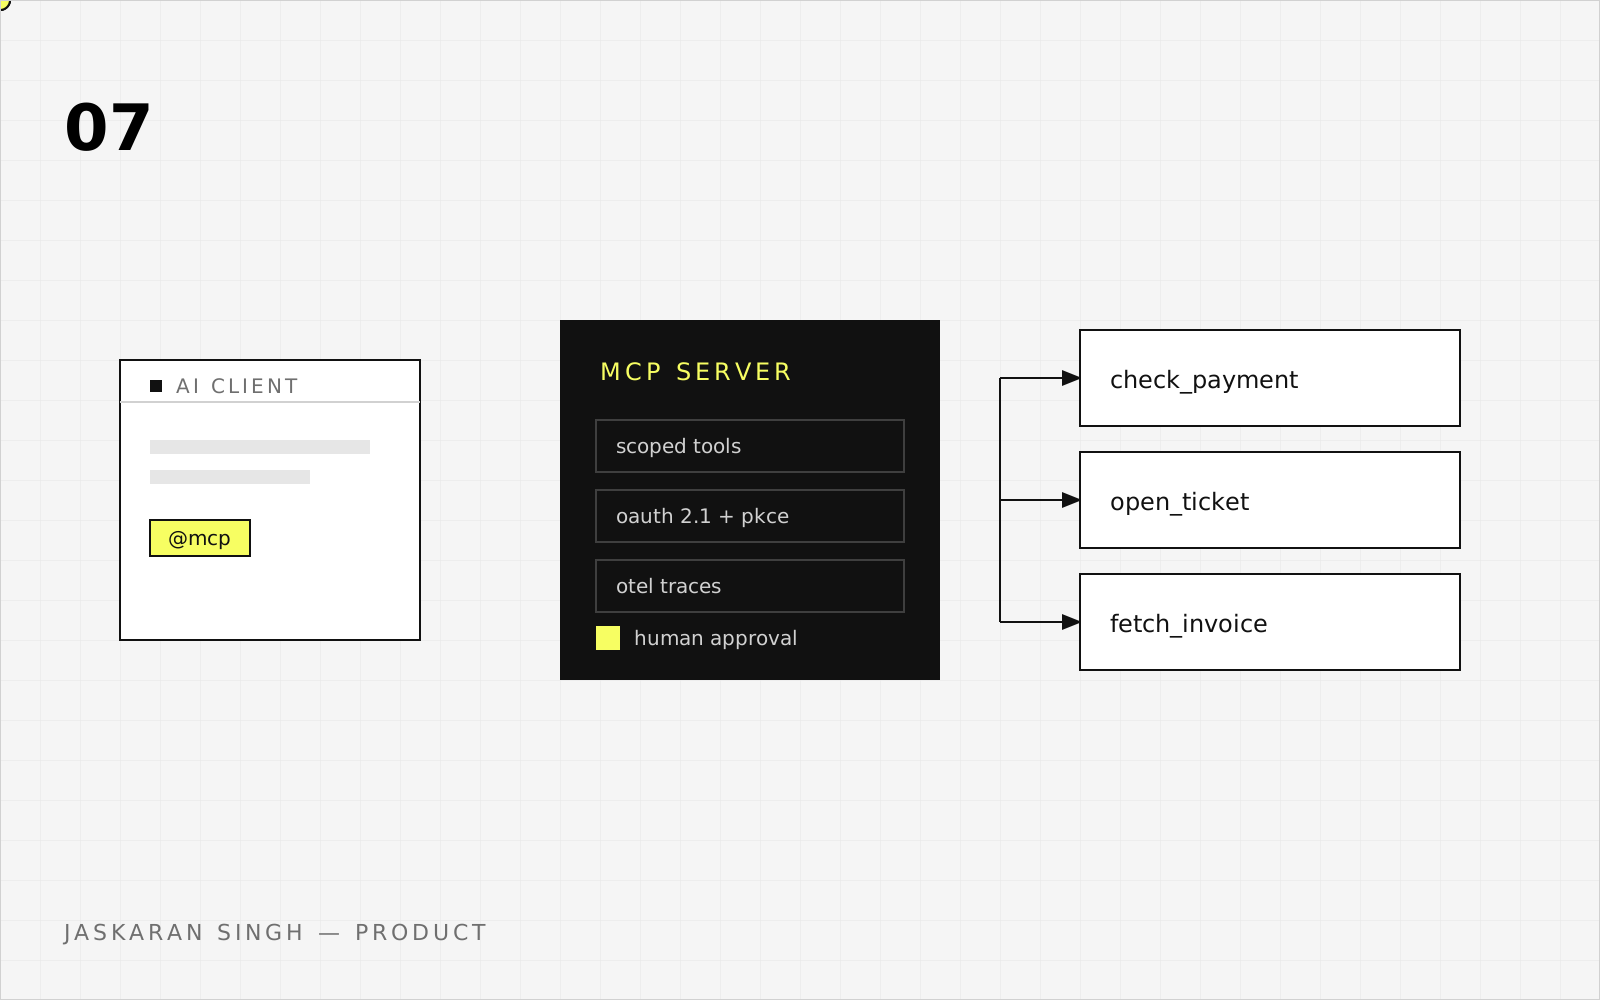
How the protocol actually works
MCP is a JSON-RPC 2.0 protocol with three roles:
- Host — the AI application the user is talking to: Claude, ChatGPT, an IDE. It owns the conversation, the permission prompts and the UI.
- Client — the connector inside that host. One client maintains one connection to one server and translates between the model's requests and the wire protocol.
- Server — your code. It advertises what it can do and executes the calls.
MCP does not replace your API. It is a typed, discoverable front door to it, with the model as the caller — your endpoints stay where they are, and the server decides which of them a given caller ever gets to see.
Three primitives
| Primitive | What it is | Who drives it | Example |
|---|---|---|---|
| Tools | Functions the model can call | The model | check_payment, open_ticket |
| Resources | Data the model or user can read | The host | Invoices, docs, database records |
| Prompts | Reusable templates and workflows | The user | A refund-review runbook |
Tools are the primitive most products start with, because they map to the actions a customer would otherwise do by hand.
What one call actually looks like
Under the conversation it is JSON-RPC messages. Discovery comes first — the client asks what the server exposes, and the server answers with tool definitions whose inputs are JSON Schema:
{
  "name": "check_payment",
  "description": "Look up the current status of a payment.",
  "inputSchema": {
    "type": "object",
    "properties": {
      "payment_id": { "type": "string" }
    },
    "required": ["payment_id"]
  },
  "annotations": {
    "readOnlyHint": true,
    "destructiveHint": false
  }
}
The call itself is one request:
{
  "jsonrpc": "2.0",
  "id": 1,
  "method": "tools/call",
  "params": {
    "name": "check_payment",
    "arguments": { "payment_id": "pay_2Nc8" }
  }
}
And one result:
{
  "jsonrpc": "2.0",
  "id": 1,
  "result": {
    "content": [
      { "type": "text", "text": "Payment pay_2Nc8 is settled." }
    ],
    "isError": false
  }
}
Two details worth understanding before you build. First, isError marks a tool-level failure — bad input, payment not found — which the model reads and can correct from or ask about, while a malformed message returns a protocol-level JSON-RPC error the model cannot recover from. Where you put the boundary between the two is a design decision, and getting it wrong is the most common cause of agents that give up too early. Second, annotations (added in the 2025-03-26 revision) tell the client what a call does before it runs: a read-only lookup can proceed, a destructive one can be held for human approval.
Transports and lifecycle
Two transports carry these messages. stdio for servers launched as local subprocesses — no network, no auth handshake, running on the user's own machine. Streamable HTTP for remote servers: a single POST endpoint that can also stream server-sent events back. The older HTTP+SSE transport is deprecated — if a vendor pitches you an SSE-only server, that is a red flag on protocol hygiene.
Until July 2026, every session began with an initialize handshake that negotiated protocol version and capabilities, followed by a session identifier on the wire. The 2026-07-28 revision removed all of that: the protocol core is now stateless, each request carries its protocol version and client capabilities in _meta, and a new server/discover call replaces the handshake. What survives is the shape of the exchange — discover, call, result — running as ordinary HTTP that any load balancer, cache or CDN already understands.
How the spec got here
The spec has moved fast, and the version history explains most of what vendors promise:
| Revision | What changed |
|---|---|
2024-11-05 | The first public spec: roles, the three primitives, stdio and HTTP+SSE transports. Shipped with Anthropic's launch announcement in November 2024. |
2025-03-26 | The security and transport release: OAuth 2.1 authorization framework with PKCE, the Streamable HTTP transport, JSON-RPC batching, and tool annotations. |
2025-06-18 | Structured tool output, elicitation (the server asking the user a question mid-call), resource indicators per RFC 8707, batching removed, and the first dedicated security best-practices guidance. |
2025-11-25 | OIDC discovery, incremental consent, URL-mode elicitation, Client ID Metadata Documents, and experimental async Tasks for long-running operations. |
2026-07-28 | The current revision: stateless core (no initialize handshake), server/discover, multi round-trip requests replacing server-initiated sampling and elicitation, cacheable list results with TTL hints, a formal extensions framework, issuer validation (iss per RFC 9207), client-credential binding, and OpenTelemetry trace context in _meta. Roots, Sampling and Logging are deprecated, behind a new feature lifecycle policy with a 12-month window. |
The protocol is converging on "plain HTTP with typed tools" — which is exactly what makes it deployable on ordinary infrastructure. It is also why the migration story matters: a server written against the old handshake keeps working, but the interesting new patterns — stateless scaling, cached discovery, extensions — assume the current revision.
The business case
The argument for an MCP server is distribution, not technology. Every assistant your customer uses is a front door, and when someone asks "did my payment go through?", exactly one product gets to answer it. The old calculus — a private integration for each assistant, a plugin per client, a bespoke API for each — collapses into one server per product and one protocol per client. That is the whole economic claim: you pay for the first integration, and every client after it is free.
The numbers, with sources
MCP's growth is measurable, and the careful numbers are strong enough without the inflated ones:
- 10,000+ active public servers — Anthropic's 9 December 2025 ecosystem update, published the day MCP was donated to the Linux Foundation's Agentic AI Foundation (co-founded by Anthropic, Block and OpenAI; Google, Microsoft and AWS among its supporters).
- 97M+ monthly SDK downloads across Python and TypeScript — same source. The first month after launch saw roughly 100,000. That is ~970× growth in about 13 months (November 2024 to December 2025).
- ~9,652 latest-version records in the official MCP registry (May 2026 snapshot), plus 15,926 GitHub repositories tagged
mcp-serverand ~90k stars on the referencemodelcontextprotocol/serversrepo (September 2026). - 45% of surveyed software organizations are in some form of production with MCP — 26% limited, 19% broad — per Stacklok's State of MCP in Software 2026 (100 senior software leaders, surveyed December 2025). The cross-industry figure across all 300 leaders — software, financial services, retail — is 41% (29% limited, 12% broad). Beware the "78% of enterprises use MCP" stat that circulates; it has no traceable source.
Platform support
This is the part with the strongest evidence, because every vendor documents it first-party: ChatGPT (connectors and remote MCP servers via the Responses API), Claude (the original client), Gemini (SDK tool support), Microsoft Copilot Studio, VS Code, Cursor, GitHub (official server since April 2025), Vercel (deployment + client SDK). Stripe, Linear, Sentry, Notion, Figma and Slack publish servers. Your customer's assistant is already reaching for whichever of them answers the question — the only decision left is whether your product is one of them.
What to measure after launch
Once it ships, the metrics that matter are unglamorous: how often the client picks your tools over a generic search, how many calls fail schema validation (that is your tool descriptions lying to the model), and how many questions that used to become support tickets now resolve inside the conversation.
When it is not the right move
Not every product should ship one. Start smaller, or wait, when:
- Your users do not work in AI apps. The channel pays off where people already ask questions in a chat. If your buyers live in your dashboard and nowhere else, the traffic will not come.
- The API is still moving. Tool definitions are a contract a model will call repeatedly within a session. If endpoints and payloads change weekly, you get failed calls and confident wrong answers instead of value.
- The task needs the whole product. Work that only makes sense with your full UI — reviewing a visual diff, dragging a timeline — gets worse when an agent has to approximate it with five tool calls.
The build-versus-buy line sits here too. A first server can be thin: five tools over an existing API. What takes the time is not the plumbing — it is permissions, error messages a model can act on, and the review.
The part your security team will ask about
The obvious way to build this is also the dangerous one: hand the AI client an API key and let it call your API directly. It works in the demo. Then someone asks what happens when the model misunderstands — or when a malicious instruction hides in a document the assistant reads and tells it to issue a refund. That question is arriving in security reviews right now, and it is where most AI integrations get stuck. Stacklok's survey names security as the top adoption barrier, ahead of cost and legacy integration.
What makes an MCP server reviewable is that the control points live in the protocol itself rather than in a wrapper you invented:
- Authorization, scoped per caller. Remote servers authenticate through the spec's authorization framework: OAuth 2.1 with PKCE, in place since the 2025-03-26 revision. The current revision adds issuer validation (
iss, per RFC 9207) and binds client credentials to the authorization server that issued them, so a token presented to the wrong server is rejected. - A tool surface you choose. The agent can only call what
tools/listreturns — that list is your API. Expose five tools instead of forty endpoints, and the blast radius of a confused model is five calls. The annotations above tell the client which of them write. - Approval gates for anything that changes state. Elicitation (2025-06-18) and, in the current revision, multi round-trip requests let a server return
input_requiredand ask the human — this refund? this send? — before the call proceeds. Refunds, deploys and outbound messages belong behind that gate. - Traces you can follow. The spec documents OpenTelemetry trace-context propagation in
_meta, so a tool call carries the same trace as the rest of the request path and shows up in the observability stack you already run.
That set — a surface you define, authorization in the protocol, approval where it matters, calls you can trace — is the difference between "an agent with access to our systems" and a feature you can take to security review.
What good looks like in production
The enterprise pattern that survives contact with a security review is staged:
- Read-only first. Docs search, analytics, issue tracking, repository search. High value, low blast radius.
- Write actions behind approval gates. Human-in-the-loop for refunds, sends, deployments. The spec's elicitation and (now) multi round-trip requests exist precisely for this.
- Scope per customer or per plan. What a free-tier caller can reach is not what an enterprise caller can reach.
- Log everything, trace what matters. Structured logs for every call, OpenTelemetry propagation for the ones you need to follow across services.
If you want to move
The shortest path from here:
- List the actions, not the endpoints. Pick the handful of things a customer would ask for — check a balance, open a ticket, track a shipment. Those become the tools.
- Decide what each caller can reach. Scope per customer or per plan. Everything else never exists to the agent.
- Handle authentication the way the spec expects. Local servers over
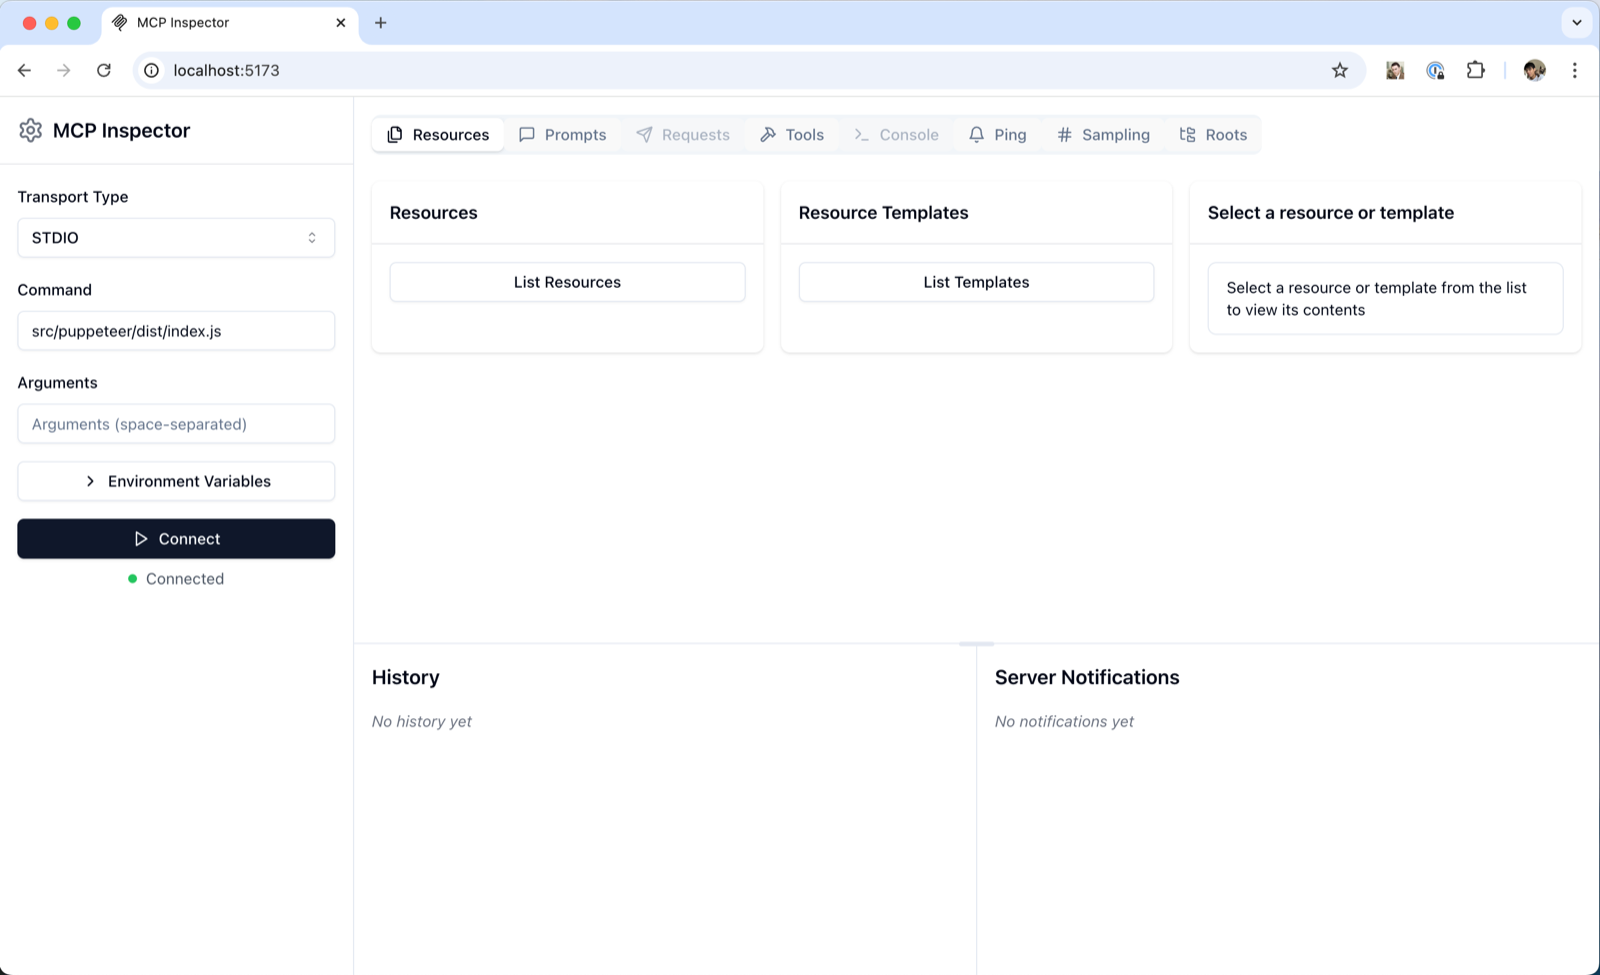
stdiorun as the user; remote servers use OAuth 2.1 with PKCE. Log every call with trace context either way. - Test with the Inspector. The official MCP Inspector connects to your server locally and exercises every tool before a real client ever sees it.
- Start with one client. Claude or Cursor. One server works with all of them, so the first integration is the expensive one — and the second costs you nothing.
I build MCP servers for companies that want this channel without the security review becoming its own project — and I use this site's own MCP tooling daily. If that is the year ahead for your product, book a call.
Sources and further reading
The specification
- MCP specification, 2026-07-28 (current revision)
- Changelogs: 2026-07-28, 2025-11-25, 2025-06-18, 2025-03-26
Building and testing
Security
Evidence and ecosystem
- Anthropic: Donating the Model Context Protocol and establishing the Agentic AI Foundation (9 Dec 2025) — the 10,000+ servers and 97M+ monthly downloads figures.
- Linux Foundation: formation of the Agentic AI Foundation — governance and founding members.
- Stacklok: State of MCP in Software 2026 — the 45% software / 41% cross-industry production figures (survey of 300 leaders, December 2025) and security as the top adoption barrier.
- Official MCP Registry — latest-version server records (9,652 at the May 2026 snapshot).
- GitHub Changelog: GitHub MCP Server public preview (April 2025) — the first-party evidence for GitHub's official server.
Comments
Discussion
Questions and notes on “Why your product needs an MCP server”
Loading comments…